Cloud Computing

Cloud Infrastructure Optimization Best Practices for Modern DevOps Environments

Guy Brodetzki
Mar 26, 2026
·
6 min read

Key Takeaways

  • Cloud infrastructure optimization is now a continuous engineering discipline, not a one-time cleanup project, organizations that treat it as quarterly housekeeping routinely overpay.
  • The most common sources of cloud waste are overprovisioned compute, idle resources, and misconfigured Kubernetes clusters - all of which are solvable with the right visibility and automation in place.
  • Effective cloud infrastructure cost optimization strategies combine rightsizing, commitment management, autoscaling tuning, and storage lifecycle policies into a consistent, repeatable practice.
  • DevOps teams can embed cost controls directly into CI/CD pipelines, shifting optimization left so it happens before waste reaches production.
  • Platforms like InfrOS are designed to automate and enforce infrastructure optimization continuously, aligning your cloud spend with your actual business needs.

Why Cloud Infrastructure Optimization Is No Longer Optional

Cloud adoption moved fast. For most organizations, that speed came at a cost: environments built in a hurry, provisioned conservatively to avoid downtime, and never fully revisited. The result is a sprawling infrastructure that delivers less than it costs.

‍

According to industry estimates, organizations waste between 30% and 35% of their cloud spend on idle or underutilized resources. That number climbs higher in multi-cloud and Kubernetes-heavy environments, where visibility breaks down across team boundaries.

‍

The shift from on-prem to cloud was supposed to unlock efficiency. In many cases, it hasn't, because the tools and habits used to manage physical infrastructure don't map to the dynamic, metered reality of cloud. Cloud infrastructure cost optimization isn't a cost-cutting measure. It's a discipline that ensures your infrastructure actually serves your business rather than outpacing it.

‍

For engineering managers and FinOps teams, this matters more than ever. Cloud budgets now sit alongside headcount as a major line item. Boards and CFOs want accountability. And the engineering teams building and running infrastructure are increasingly the ones being asked to explain the bill.

‍

The most effective organizations are responding with a fundamentally different approach: shift-left optimization. Rather than deploying infrastructure and then reactively fixing the cost and performance issues that emerge, they design correctly from the start - simulating, benchmarking, and validating infrastructure before a single resource is provisioned. Optimization built into the design phase is cheaper, faster, and more reliable than optimization performed after the fact.

Core Drivers of Cloud Infrastructure Cost Inefficiency

Before you can fix a problem, you need to understand where it lives. Most cloud cost inefficiency traces back to a handful of predictable patterns.

‍

Overprovisioned Compute

‍

When teams size infrastructure for peak load or worst-case scenarios, they lock in resources that sit idle most of the time. A VM provisioned for a batch job that runs three hours a day is burning money for the other twenty-one. This is one of the most common, and most fixable, sources of waste.

‍

Idle and Orphaned Resources

‍

Cloud environments accumulate technical debt quickly. Snapshots, load balancers, reserved IPs, and storage volumes tied to workloads that no longer exist quietly generate charges with no one noticing. Without a systematic review process, these orphaned resources compound over time.

‍

Inefficient Autoscaling Configurations

‍

Autoscaling is one of the most valuable features in cloud infrastructure, and one of the most misused. Scaling thresholds set too conservatively prevent cost savings from ever materializing. Scaling triggers that react too slowly leave your application struggling under load while the bill climbs. Getting autoscaling right requires tuning based on real traffic patterns, not defaults.

‍

Misconfigured Kubernetes Clusters

‍

Kubernetes adds power and flexibility to infrastructure, but also a new layer of complexity that directly affects cost. CPU and memory requests set without analysis lead to wasted node capacity. Namespace-level cost visibility is often absent. Persistent volumes outlive their workloads. Many organizations running Kubernetes have limited visibility into what their clusters actually cost at the service or team level.

‍

Unmanaged Commitment Strategies

‍

Cloud providers offer significant discounts for committed usage, Reserved Instances on AWS, Committed Use Discounts on GCP, Reserved Capacity on Azure. Teams that haven't developed a disciplined approach to commitment purchasing consistently pay on-demand rates for workloads that have been running steadily for months or years.

Proven Cloud Infrastructure Cost Optimization Strategies

The most resilient approach to cloud infrastructure cost optimization is designing infrastructure correctly before it ships, not patching it afterward. Shift-left optimization means treating cost, performance, and reliability as design constraints, not post-deployment concerns. The strategies below operate at two levels: getting new infrastructure right from the start, and continuously improving what's already running.

‍

Rightsizing Compute Resources

‍

Rightsizing means matching instance types and sizes to actual utilization, not projected maximums. Start by pulling two to four weeks of CPU and memory utilization data across your compute inventory. Identify instances running consistently below 40% utilization. Downsize them, test for performance impact, and iterate. Done systematically, rightsizing alone can reduce compute costs by 20–30% without any change to architecture.

‍

Autoscaling Tuning

‍

Revisit every autoscaling policy with actual traffic data in hand. Set scale-out thresholds based on observed peak demand rather than worst-case assumptions. Build in scale-in aggressiveness, many defaults are too conservative and leave over-provisioned capacity running during low-traffic windows. For Kubernetes, review Horizontal Pod Autoscaler settings per workload and ensure Vertical Pod Autoscaler recommendations are factored into resource requests.

‍

Commitment Management

‍

Develop a rolling commitment strategy: analyze which workloads have run steadily for 90 days or more and convert those to reserved or committed pricing. Review commitments quarterly. Use Savings Plans on AWS for flexibility across instance families, and layer spot or preemptible instances for non-critical, fault-tolerant workloads like batch processing, CI/CD jobs, and data pipelines.

‍

Storage Lifecycle Policies

‍

Most organizations have no enforced policy for what happens to data after it's no longer actively used. Implement tiering: move infrequently accessed data to lower-cost storage classes automatically. Set expiry policies on snapshots. Archive or delete log data beyond a defined retention window. Storage optimization tends to have a quieter ROI than compute, but it accumulates meaningfully at scale.

‍

Workload Scheduling

‍

Not all workloads need to run around the clock. Development and staging environments, scheduled jobs, and batch workloads that run overnight can be stopped during off-hours and weekends. Even simple scheduling automation can cut non-production environment costs by 60–70%.

Cost Optimization Tips for Cloud Infrastructure in DevOps Environments

Optimization works best when it's embedded into the way teams work every day, ideally before infrastructure is deployed at all. The shift-left model means catching cost and performance issues at the design and code review stage, not after they've been running in production for weeks. Here are practical ways engineering teams can make that real.

  • Validate and benchmark infrastructure before deploying it. The most effective way to avoid production optimization problems is to not introduce them in the first place. Tools like InfrOS emulate the target environment to verify that generated IaC is actually deployable and benchmark it against performance and cost targets before a single resource is provisioned. This eliminates an entire class of reactive fixes.
  • Define resource request standards for Kubernetes. Establish organization-wide defaults for CPU and memory requests and limits. Enforce them through admission policies so under-specified workloads don't make it to production.
  • Include cost impact in infrastructure pull requests. Tooling exists to estimate the cost delta of infrastructure changes before they're merged. Building this into CI/CD gives engineers real-time feedback and creates a culture of cost awareness without requiring a separate review process.
  • Tag everything from day one. Cost allocation only works if your resources are consistently tagged by environment, team, service, and cost center. Make tagging a deployment requirement, not an afterthought. Untagged resources should fail validation in your IaC pipeline.
  • Set up anomaly detection alerts. All major cloud providers offer cost anomaly detection. Enable it, tune the sensitivity, and route alerts to the engineering team that owns the affected resources, not just the FinOps or finance team.
  • Review cloud costs in engineering standups. Cost should be a first-class metric alongside latency, error rate, and deployment frequency. A weekly cost review, even a brief one, builds accountability and surfaces waste before it compounds.
  • Automate idle resource cleanup. Use policies or tooling to detect and flag, or automatically terminate, resources that have been idle for more than a defined threshold. This applies to stopped instances, unused load balancers, unattached volumes, and stale snapshots.

FAQ

How often should cloud infrastructure cost optimization be performed?

‍

More often than most teams realize. Even if your workloads don't change, your cloud environment does, providers continuously update pricing, introduce new instance types, retire older ones, and launch services that can replace more expensive configurations. What was the optimal setup six months ago may no longer be. Beyond reactive reviews, teams should treat optimization as a continuous background process: weekly cost review cadences, automated anomaly alerts, and tooling that monitors infrastructure drift in near real-time rather than waiting for a quarterly audit to surface waste.

‍

Is infrastructure-level optimization safe for production workloads?

‍

Yes, and the safest way to get there is to validate infrastructure before it reaches production in the first place. Platforms like InfrOS emulate the target environment and benchmark generated IaC against performance and cost targets prior to deployment, so issues are caught at the design stage rather than after they're live. For optimizing existing production workloads, the approach is incremental: test in lower environments first, monitor performance closely after each change, and adjust gradually rather than making sweeping modifications at once.

‍

How does Kubernetes affect cloud infrastructure optimization?

‍

Kubernetes introduces a layer of cost complexity that sits between your applications and the underlying cloud infrastructure. Poorly configured resource requests and limits lead to over-provisioned or under-utilized nodes. Namespace-level cost attribution is often missing by default. Effective cloud infrastructure optimization in Kubernetes environments requires dedicated visibility tools and consistent resource governance policies across clusters.

‍

What metrics matter most for cloud infrastructure cost optimization?

‍

The most actionable metrics are CPU and memory utilization per instance or pod, cost per unit of business output (unit economics), idle resource percentage, commitment coverage ratio, and storage utilization by tier. Tracking these consistently allows teams to prioritize optimization efforts by impact rather than guessing where waste lives.

‍

Can optimization reduce performance risks while lowering costs?

‍

Yes, and this is one of the most misunderstood aspects of infrastructure optimization. Oversized, misconfigured environments often perform worse than well-tuned ones. Fixing autoscaling policies improves responsiveness. Eliminating idle resources reduces noise in monitoring. Proper Kubernetes configuration improves scheduling efficiency. Done right, optimization improves reliability and performance while reducing spend.
‍

Keep on reading

InfrOS
InfrOS Joins the Microsoft for Startups Pegasus Program
Naor Porat
Nov 19, 2026
·
6 min read

InfrOS is excited to announce its acceptance into the Microsoft for Startups Pegasus Program. This collaboration provides InfrOS with access to powerful AI tools, Azure credits, and a global customer network to help scale faster and smarter.

‍

We’re excited to welcome InfrOS to the Microsoft for Startups Pegasus Program. This initiative gives select startups access to Azure’s cutting-edge AI models, enterprise-grade security and privacy, and unique go-to-market support to accelerate growth. Through Pegasus, startups can build fast, scale smart, and sell more by tapping into the full power of Azure and the Microsoft ecosystem

- Tom Davis, General Manager, Microsoft for Startups

‍

Look out for more exciting news in the near future!

‍

Cloud Architecture Design
Why Configuration Drift Breaks Production and How Teams Prevent It
Guy Brodetzki
Nov 12, 2026
·
6 min read

Cloud environment changes with every single modification. Various new services are added; changes in configurations occur; infrastructure changes to accommodate various load capacities. Such modifications are necessary, but they involve opportunities for the inconsistency within the environment.

‍

The configuration that was performed during the staging phase will never appear in the production phase, while the fix to the issue in the production phase will never appear in the infrastructure configuration.

This process is referred to as the configuration drift and the understanding of its reasons and prevention is needed to provide consistency of the cloud environment.

Key Takeaways

  • Configuration drift is described as a state where the implemented infrastructure does not conform to the configuration required anymore, especially after making manual changes, temporary fixes, and inconsistent deployments.
  • The staging and production environments should have consistent configurations and operations despite having different resource capacities and size requirements.
  • With infrastructure as code, automation testing, and deployment processes, teams can avoid recurring drift.
  • Detecting drift involves detecting inconsistencies, and teams have to understand their effects before solving them.
  • InfrOS is an application that enables teams to assess architecture decisions before implementing them and consistently check for infrastructural consistency.

What Is Configuration Drift, and Why Does It Happen?

Configuration Drift is a term for the gap between the expected and actual configurations of the infrastructure. Consider, for example, an engineering team deploying an application through Terraform. The configuration specifies all the resources required by the application: servers, network, storage, database, and security settings.

‍

Everything corresponds to the expected configuration at first. However, after a couple of weeks, an engineer adjusts one of the network rules to fix a problem. Another engineer scales up a database in order to improve its performance. Both adjustments might be necessary, yet none of them are captured in the initial infrastructure configuration. The resulting environment deviates from the expectations of the engineering team.

‍

It raises uncertainty: the next deployment can undo the changes made, and engineers looking through the configuration files can rely on the outdated settings. The term configuration drift is widely used in the cloud environment due to the frequent changing of infrastructure. Resources are being added, resized, replaced, and reconfigured according to the evolving application. Moreover, one should differentiate configuration drift from the architectural drift.

‍

The former relates to the settings of individual resources while the latter implies deviation of the whole infrastructure structure, dependencies, and behavior. Both make cloud environments harder to manage, but architectural drift often requires broader changes than simply restoring individual settings.

Why Does Infrastructure Drift After Every Release?

Releases cause modifications in both applications and the underlying infrastructure. Ideally, this should be the case regardless of whether development, staging, or production environments are being referred to. In reality, this does not always apply.

‍

Sometimes, a developer makes a change in the staging environment to get the release working properly. The application gets through its tests but the modification in the infrastructure is never added to the deployment package. By the time the application is deployed to production, it acts differently due to the lack of the required setting. It may also occur the other way around, where a manual change was made in the production environment and nothing gets changed in staging.

‍

There are several reasons for that.

- Manual changes: Engineers modify resources directly through cloud consoles instead of updating the infrastructure definition.

- Environment-specific settings: Different variables, permissions, or networking configurations create differences that are difficult to track.

- Emergency fixes: Temporary changes made during incidents remain active without being documented.

- Inconsistent deployment processes: Different teams use different scripts, tools, or procedures to update infrastructure.

‍

These issues become more common as environments grow and release frequency increases. However, drift is not an unavoidable consequence of frequent deployment. It becomes a recurring problem when teams lack a consistent way to define, validate, and promote infrastructure changes. The goal is to make every release predictable, regardless of how often changes occur.

How Do I Keep My Cloud Environments in Sync?

Keeping cloud environments aligned does not mean making development, staging, and production identical. Production may need more compute capacity, stricter security controls, or higher availability than staging. These differences are expected. What matters is that differences are intentional, documented, and managed through the same process.

There are several principles that make this possible.

‍

Use one consistent infrastructure definition

The practice of infrastructure as code enables teams to define resources via version-controlled configurations instead of creating resources manually. A common template and/or module will ensure that each environment is following the same architecture design, while specific environmental variables will control any difference between the environments, such as resource size. This will make comparison easier and minimize any risk of undocumented modifications.

‍

Deploy through consistent processes

Changes to infrastructure should occur via a reusable deployment pipeline. Teams should not deploy changes directly to production; rather, they should promote changes after review via testing and staging. Whenever possible, the same version of the application artifact and infrastructure configuration should be used. This allows you to guarantee that what has been tested is what will be deployed.

‍

Treat staging as a meaningful production test

The process of staging must reflect those dependencies, assumptions, and infrastructure behaviors that are present in production. It is not always required to have the same capacity, but the major differences must be known. In case the staging environment has different network policies or lacks vital services, tests in this environment mean little for production.

‍

Continuously check for differences

Even with consistent deployment processes, unexpected changes can occur. Regular drift detection helps teams compare actual infrastructure against approved definitions and investigate differences before they affect future releases. Together, these practices create an environment where changes remain controlled without slowing down development. For more on creating consistent infrastructure through better architecture practices, see our guide to Shift-Left Cloud Infrastructure Design.

What Guardrails Prevent Configuration Drift?

Guardrails are rules and processes that help teams make safe infrastructure changes without requiring manual oversight of every decision. They should prevent common mistakes while allowing engineers to respond when something genuinely needs to change.

Several guardrails are particularly useful.

‍

Version control and code reviews

Infrastructure definitions should be stored in version control, with changes reviewed before deployment. This creates a record of what changed, why it changed, and who approved it.

‍

Access controls

Restricting direct production modifications reduces the risk of undocumented changes. Emergency access can remain available, provided changes are reviewed afterward.

‍

Policy checks

Automated policies can identify configurations that violate security or operational requirements, such as missing encryption, excessive permissions, or unapproved resource locations.

‍

Automated drift detection

Regular comparisons between deployed infrastructure and approved definitions help identify unexpected changes early.

‍

Deployment approvals

Important infrastructure changes should pass defined checks before reaching production. Higher-risk changes may require additional review.

‍

Guardrails should also account for legitimate exceptions. A temporary production fix may be necessary, but it should be documented and either incorporated into the approved configuration or reversed when no longer needed. The objective is not to block change. It is to make infrastructure changes visible, consistent, and easier to manage. For a broader perspective, see our article on Cloud Governance Tools for Engineering Teams.

How Do I Validate Changes Before Promoting Them to Production?

Environmental consistency is but one piece of the puzzle. It’s equally important that teams feel confident in the behavior of new changes. An effective staging release does not necessarily imply a successful production deployment. The process of validation must start prior to any infrastructure modifications.

1. Review the proposed change

Start by identifying which resources, configurations, and dependencies will change.

Infrastructure as code tools can show proposed modifications, helping engineers identify unexpected replacements or configuration differences.

‍

2. Check policies and requirements

Validate the change against security policies, capacity requirements, and operational constraints. This helps prevent configurations that may work technically but violate important requirements.

‍

3. Test in staging

Deploy the proposed change to a representative staging environment. Check application functionality, connectivity, dependencies, and relevant performance requirements.

‍

4. Evaluate the broader impact

A change can work in isolation while creating problems elsewhere. For example, moving a service to another region may affect network latency, data transfer costs, or recovery behavior. These effects should be considered before production deployment.

‍

5. Promote the approved change

After successful validation, push the approved configuration and application artifacts according to the deployment process defined previously. Watch for any issues with the release and have fallback or recovery options in place. The main idea behind this is straightforward: infrastructure changes must be validated prior to being introduced into production, not only after an issue occurred.

What Should I Use If My Architecture Drifts Every Release?

If there are unexpected differences because of changes in infrastructure with every release, then the first thing to do would be finding out where these differences have originated from. Resource level configuration drift, Infrastructure as Code, automated deployment pipelines, and drift detection form a robust base for this process. Using tools like Terraform will enable you to manage approved configurations and find differences in the managed infrastructure.

‍

But recurring drift can also mean that there is a more serious problem at hand. If engineers are continually increasing capacity, changing service connections, and network configurations, then the architecture itself might not meet the demands of the application anymore. In such cases, reverting to previous settings might be a short-term solution but the same problem will keep recurring every time there is a new release.

‍

With the help of InfrOS, engineering teams can develop, evaluate, and validate infrastructure architectures before putting them into practice. This is done by assessing architectural alternatives in terms of cost, performance, reliability, security, and complexity. Using Evolving Architecture™, InfrOS facilitates continuous architectural assessment in case of changes in workload, requirements, and cloud capabilities. This is in addition to the configuration management approach that assesses only the consistency of the resource with its initial configuration. With InfrOS, engineering teams can also assess the compliance of the architecture with its requirements. This is useful for companies facing architectural challenges on an ongoing basis. You can read more about developing these capabilities in our guide to the Enterprise Architecture Maturity Model.

FAQ

What causes configuration drift in cloud environments?

Configuration drift is typically caused by manual changes, patching, inconsistent deployment practices, and environment-specific configuration management that is not being consistently maintained. Configuration drift can occur as well because various teams implement varying approaches for managing the same infrastructure environment. As environments evolve, inconsistencies arise which create uncertainty during deployments.

‍

How do you detect infrastructure drift?

Infrastructure drift is recognized through a comparison of the actual state of the resources and the approved infrastructure definition. Tools like Terraform and cloud native configuration drift detection solutions help recognize any deviation. Routine automated monitoring assists organizations in recognizing drift before it impacts production operations, while further validation aids in determining if the modification poses a security or performance threat.

‍

Is all configuration drift bad?

It is not always bad. There could be valid business reasons for changing certain configuration parameters, such as scaling a database or adjusting networking in order to solve a particular issue. However, what makes infrastructure drift risky is the fact that the modification has no documentation or is not validated against the approved requirements.

‍

How often should you run drift detection?

It is recommended to carry out drift detection often and ideally within the context of automated deployment workflows. Important infrastructures would do well checking for drift after updates to their infrastructure, releases, and at periodic intervals. It really depends on how frequently their infrastructure changes and how tolerant of risks they are willing to accept.

‍

Can configuration drift be prevented entirely?

The level of configuration drift can be minimized to a large extent, but avoiding it completely may not be possible when you are working with dynamic cloud infrastructures. You can avoid drift through IaC practices, pipelines, automated validation, and security restrictions. Nevertheless, there will always be exceptions. Configuration drift does not merely consist of changes in configuration. This is a production risk only if an organization cannot see where things got changed, how they were changed, and if everything in its environment is operating according to expectations.

‍

By ensuring consistency in infrastructure definitions, validating changes prior to promoting them, and monitoring environments through their evolution process, engineering teams would be able to release with confidence without having to fix the same issues repeatedly. The idea is not to prevent infrastructure changes but to make sure that all changes made are intentional, validated, and consistent with the organization’s architectural requirements.

AI & Data
How to Connect Your AI Assistant to InfrOS
Harel Dil
Nov 5, 2026
·
6 min read

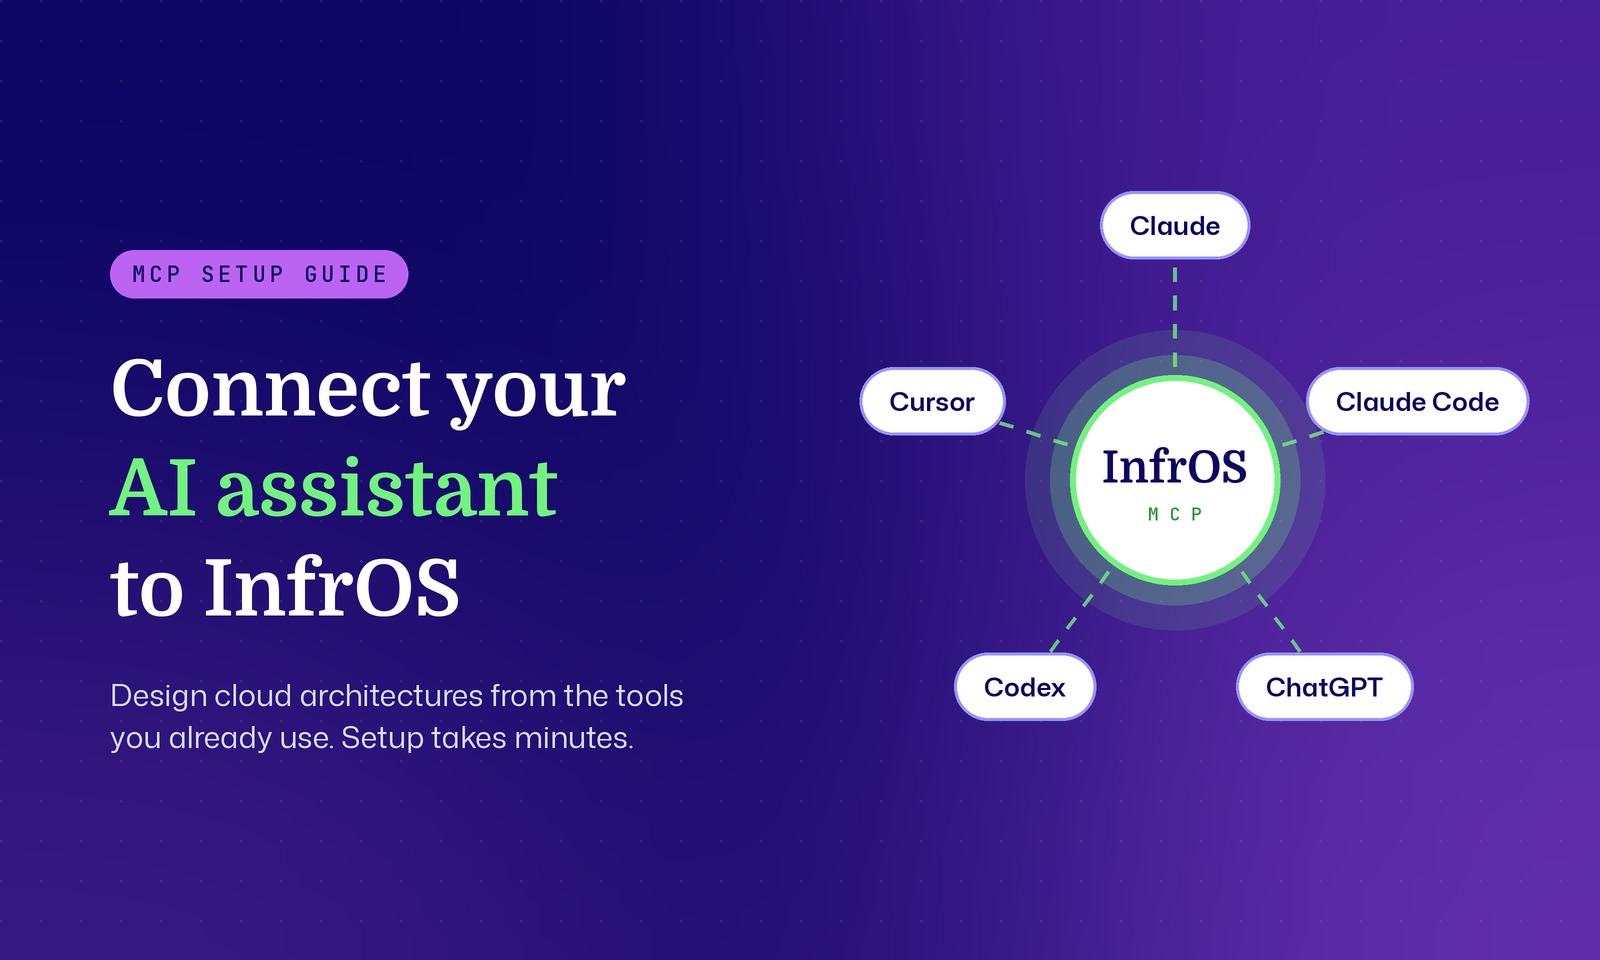
You can now use InfrOS straight from the AI assistant you already work in. Once it's connected, your assistant can design cloud architectures with you, using your own InfrOS account and permissions. No new tool to learn, and no copy-pasting between tabs.

Setup takes a few minutes. Here's everything you need.

What you need

You only need three things. First, an InfrOS account. Second, a supported assistant. Third, the InfrOS MCP address, which is https://api.app.infros.io/assistant/mcp

These assistants and plans work today:

  • Claude: Free, Pro, Max, Team and Enterprise
  • Claude Code: any plan that includes Claude Code
  • ChatGPT: Business, Enterprise and Edu
  • Codex: any ChatGPT plan that includes Codex
  • Cursor: any plan

We're adding more assistants. If yours isn't on the list, let us know.

Set it up in your assistant

Pick your assistant below and follow the steps. Every option ends the same way. You sign in to InfrOS and click Allow.

‍

Claude

  1. Open Customize, then Connectors.
  2. Click + Add, then Add custom connector.
  3. Name it InfrOS, paste the InfrOS address, then click Continue and Add.
  4. Sign in to InfrOS and click Allow.

On Team and Enterprise plans, an Owner adds InfrOS once in Organization settings, then Connectors. After that, each member just clicks Connect next to InfrOS.

‍

Claude Code

Run this in your terminal:

claude mcp add --transport http infros https://api.app.infros.io/assistant/mcp

Then type /mcp in Claude Code, choose infros, choose Authenticate, and click Allow in InfrOS.

‍

ChatGPT

  1. Open Settings, then Apps & Connectors, then Advanced settings, and turn on Developer mode.
  2. Add a connector named InfrOS with the InfrOS address, and choose OAuth to sign in.
  3. Sign in to InfrOS and click Allow.

Codex

Run these two commands:

codex mcp add infros --url https://api.app.infros.io/assistant/mcp
codex mcp login infros

Then click Allow in InfrOS.

‍

Cursor

Add InfrOS to ~/.cursor/mcp.json:

{
 "mcpServers": {
   "infros": {
     "url": "https://api.app.infros.io/assistant/mcp"
   }
 }
}

Then open Cursor's MCP settings, sign in to InfrOS, and click Allow.

What your assistant can do

You stay in control. When you connect, InfrOS shows you exactly what the assistant is asking to do. It can only do what you allow, and only what your InfrOS role already lets you do.

  • Read: see your Systems, specifications, landing zones and architecture proposals. Anyone can allow this.
  • Write: create Systems and versions, and edit drafts. Anyone can allow this.
  • Spend: start design runs and Terraform generation, which use your organization's credits. Only organization admins can allow this.
  • Admin: manage landing zones, standing constraints and GitHub repositories. Only organization admins can allow this.

Credits never get spent by surprise. Your assistant always tells you the price first and waits for you to say yes.

How to disconnect

Changed your mind? Open your Profile in InfrOS, go to Connected assistants, and click Revoke.

Try it now

Connect your assistant, then ask it to design an architecture for a real workload you're planning. It's the same InfrOS you know, just from inside your chat. Want a walkthrough first? Book a demo and we'll set it up with you.